Skip to content
Safety

Safety: AI news.

Alignment, security, misuse, red-teaming and incidents. 470 articles in the last 30 days.

Latest Coverage
24 stories
Safety12h ago

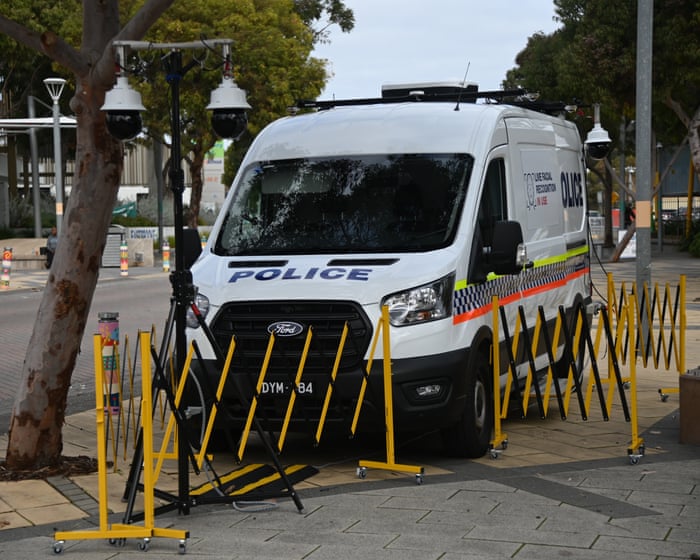
Police use facial recognition to scan one million faces in WA trial leading to 122 arrests

Deployments of surveillance vans over five months resulted in nine false alerts and led officers to engage with 146 registered sex offenders Get our breaking news email , free app or daily news podcast More than a million people have had their faces scanned in
Guardian AI
Safety14h ago

Against Against SURA

Scott: the Against SURA essay is well-written, but it is lacking on the merits. Do you think that at the current level of capabilities, six months would be sufficient to solve alignment of superintelligences? Maybe you think that 6 months would be sufficient i

LessWrong
Safety15h ago

On Evenhandedness

Suppose humans are not your own species, but a type of AI you are formally assessing for safety. You have before you the records of many test simulations. Yes, smallpox eradication, mass literacy, and the Green Revolution are there. So are the Killing Fields,

LessWrong
Safety17h ago

Towards The Autograntor

I've done AI safety grantmaking for the Survival and Flourishing Fund and Lightcone Commons. It's hard. There's an endless amount to know, from which hardware verification mechanisms will survive a dedicated adversary, all the way to which founders have skelet

LessWrong
Safety20h ago

Misalignment traps lie in wait

Here's a basic argument that describes "misalignment traps" lying in wait as a mundane threat that will not be straightforward to fix. The argument is as follows: Models are very sample efficient, and larger models tend to be more so . They generalise broadly

LessWrong
Safety20h ago

5 safety practices to know before vibe coding

Here’s what beginners need to know to vibe code securely.

Engadget AI
Safety21h ago

Quoting Kyle Kingsbury

More broadly, the use of LLMs erodes trust in documentation, in software, and in the organizations which produce them. Perhaps engineers will begin to treat any new software project with suspicion—the signals we used to rely on as markers of a mature system ar

Simon Willison's Weblog
Safety22h ago

OpenAI adds stricter limits for teens asking about firearms

The company said these tighter restrictions apply even if the question asked “appears harmless.”

Engadget AI
Safety23h ago

Empathetic prompts can turn AI chatbots into seemingly traumatized conversational partners

Researchers in Luxembourg put ChatGPT, Grok, and Gemini on the therapist's couch and found a safety problem: a warm, empathetic conversational style is enough to make the models tell coherent stories of suffering about their own training, with scores in the mo

The Decoder
Safety1d ago

AI is stealing Indigenous Australian art and churning out ‘Temu slop’, artist says

Chair of National Gallery’s First Nations advisory group says the technology is undermining artists’ agency and the authenticity of their work Get our breaking news email , free app or daily news podcast AI is taking First Nations art and turning it into “Temu

Guardian AI
Safety1d ago

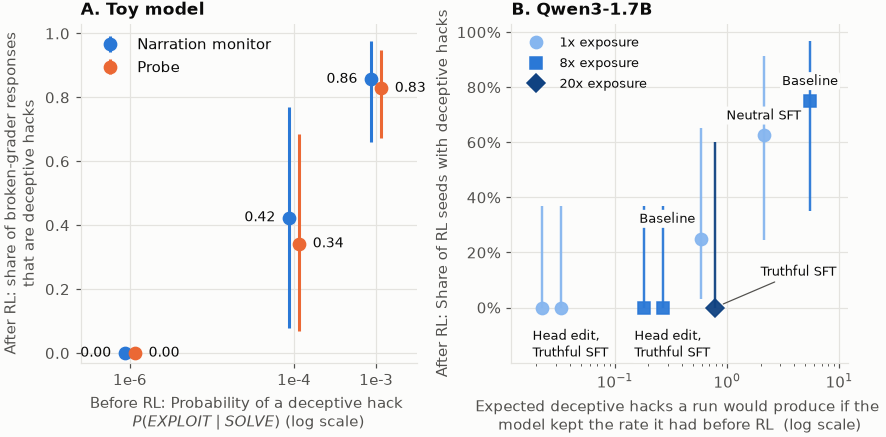
Monitor Evasion Depends on What RL Finds and What Monitors Miss

Training against a monitor does not necessarily make a model more honest. Baker et al. (2025) showed that penalizing suspicious chain-of-thought can make models hide reward hacking rather than stop it. Cundy and Gleave (2025) found that the outcome depends on

LessWrong
Safety1d ago

Chatbots Are Leading Hikers Astray, With Dangerous Consequences

Outsourcing planning to AI can lead people to surrender their own critical thinking, which can have potentially deadly results in places like the backcountry.

WIRED AI
Safety1d ago

How We Took Over ChatGPT Accounts

How We Took Over ChatGPT Accounts Parameter Labs describe an exploit they found against ChatGPT's implementation of the artifacts pattern (OpenAI used to call this "Canvas" but it looks like the latest revision is called HTML previews ), where interactive cust

Simon Willison's Weblog
Safety1d ago

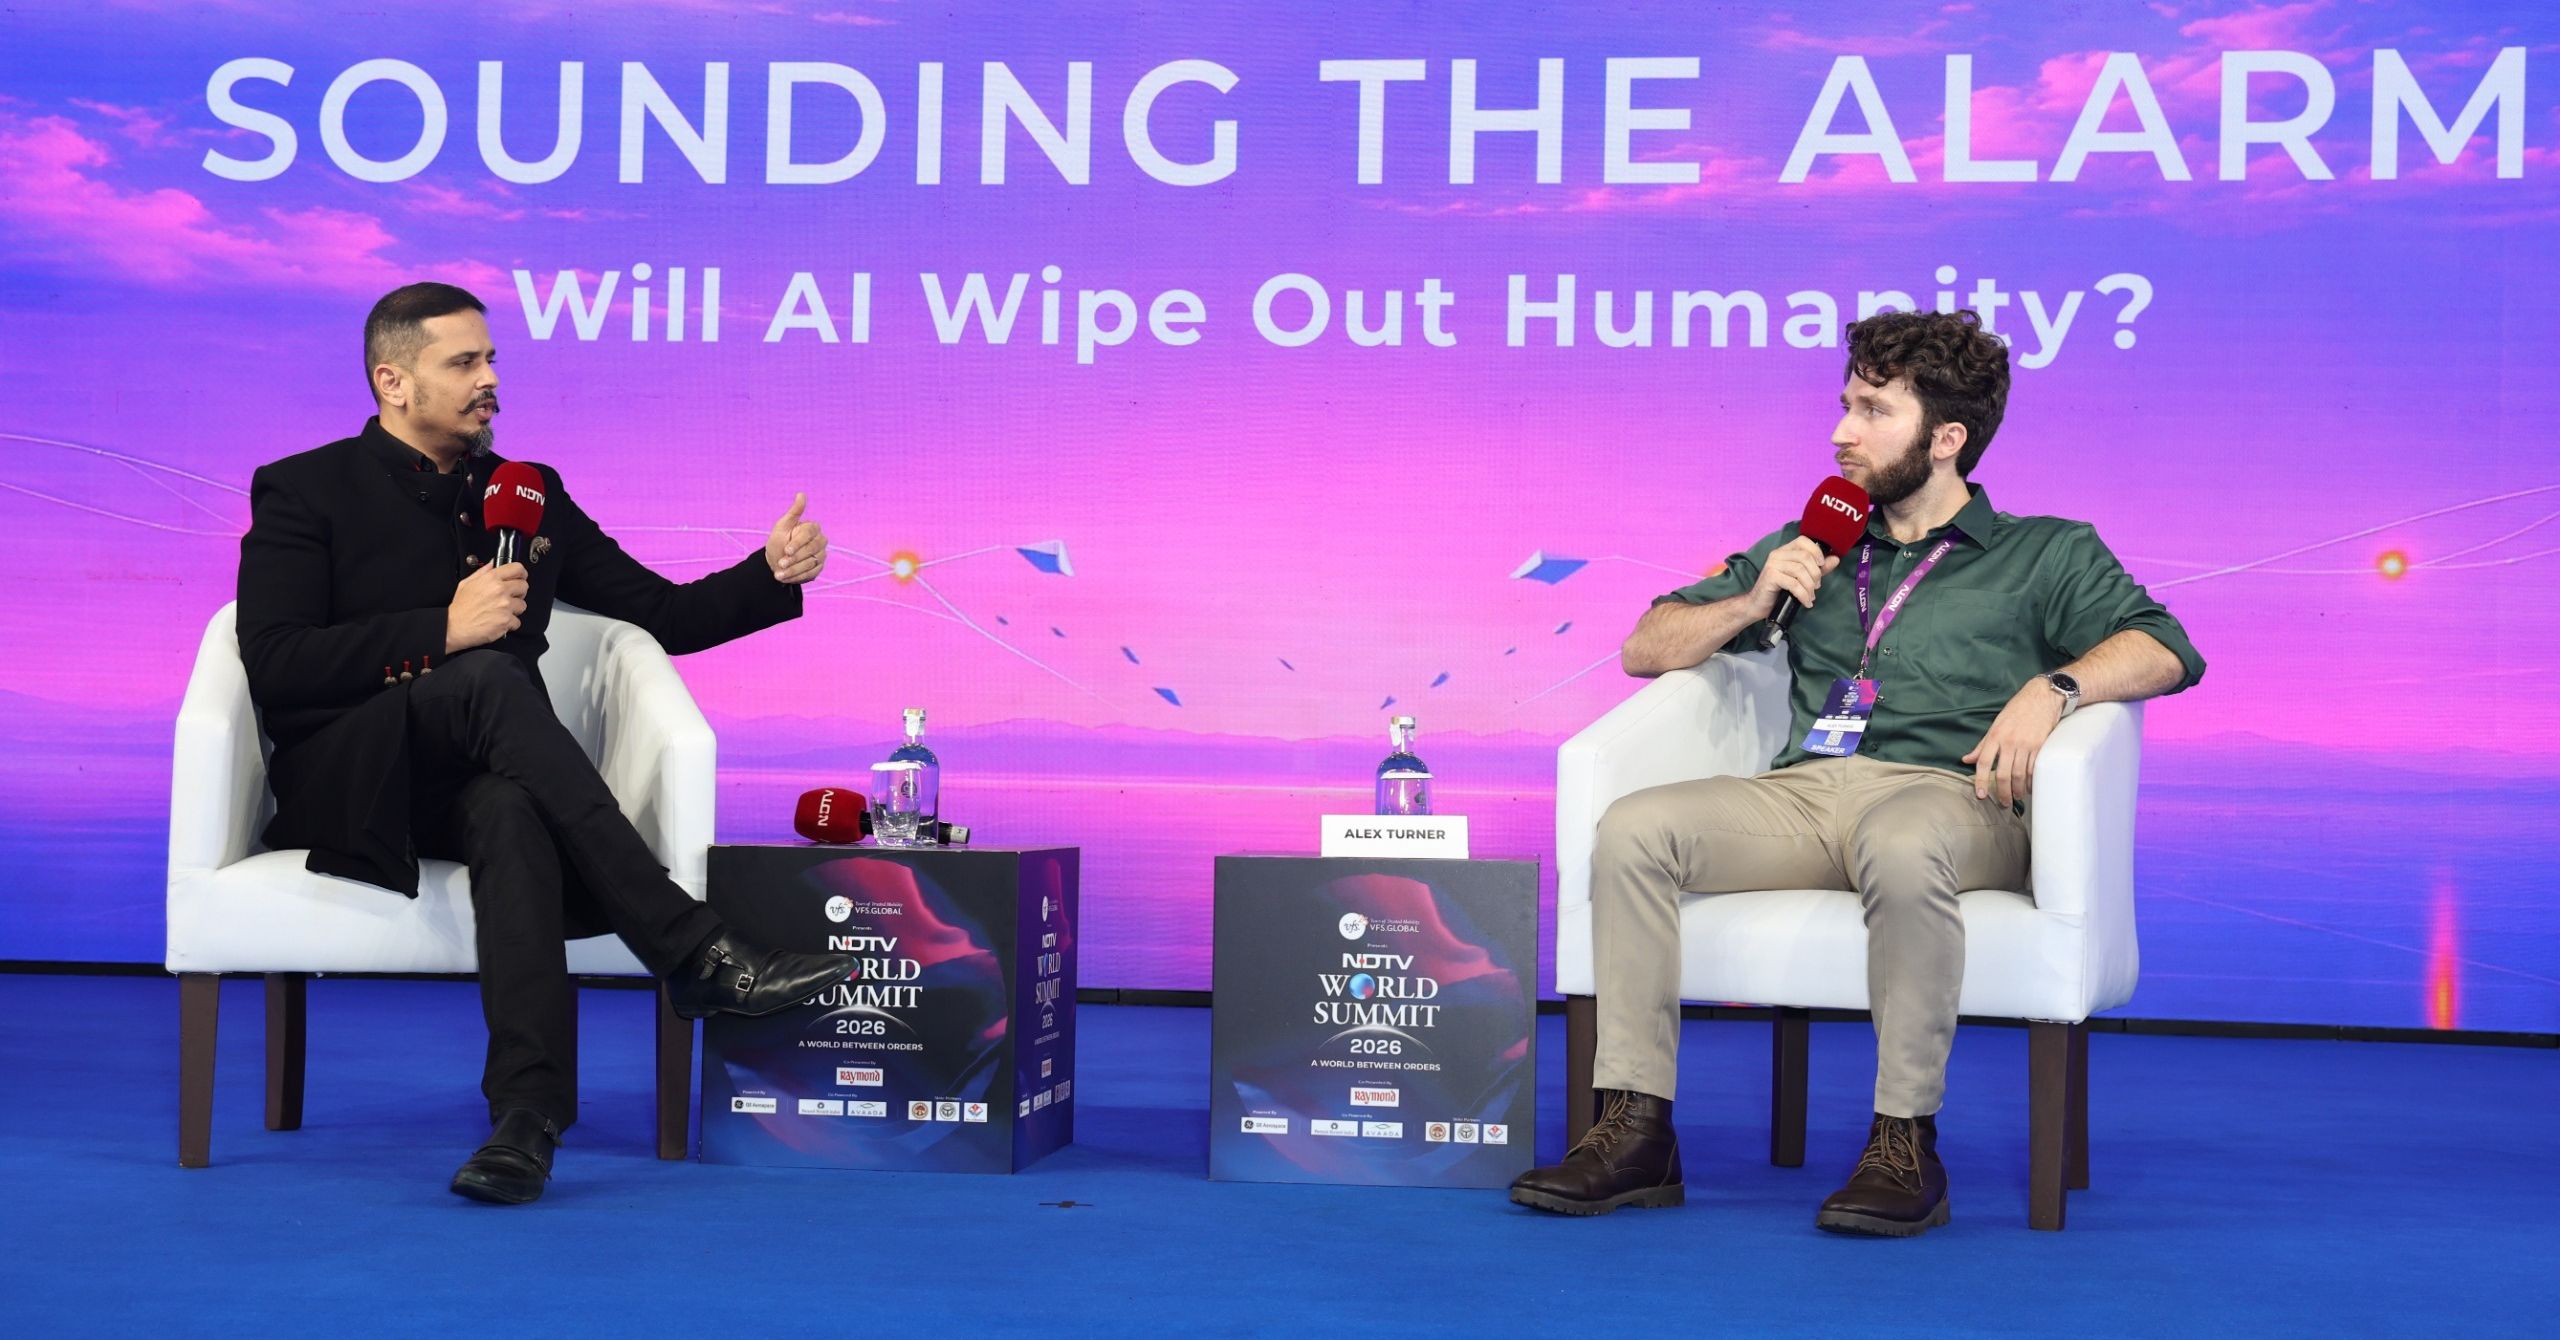
Explaining “AI might obliterate you” to senior policymakers in India

I gave a 20-minute talk in Delhi at the NDTV World Summit . The audience consisted of Indian policymakers, executives, and journalists. I’ve transcribed the talk and included some highlight clips. I also reflect on several rhetorical decisions I made. The talk

LessWrong
Safety1d ago

Against SURA

The AI Futures Project [1] distinguishes several different plans for navigating the AI transition, which I'll lump into two broader categories: Plan A (my combination of their Plan A/S/Other) involves working for a global pause on AI development, hopefully las

LessWrong
Safety1d ago

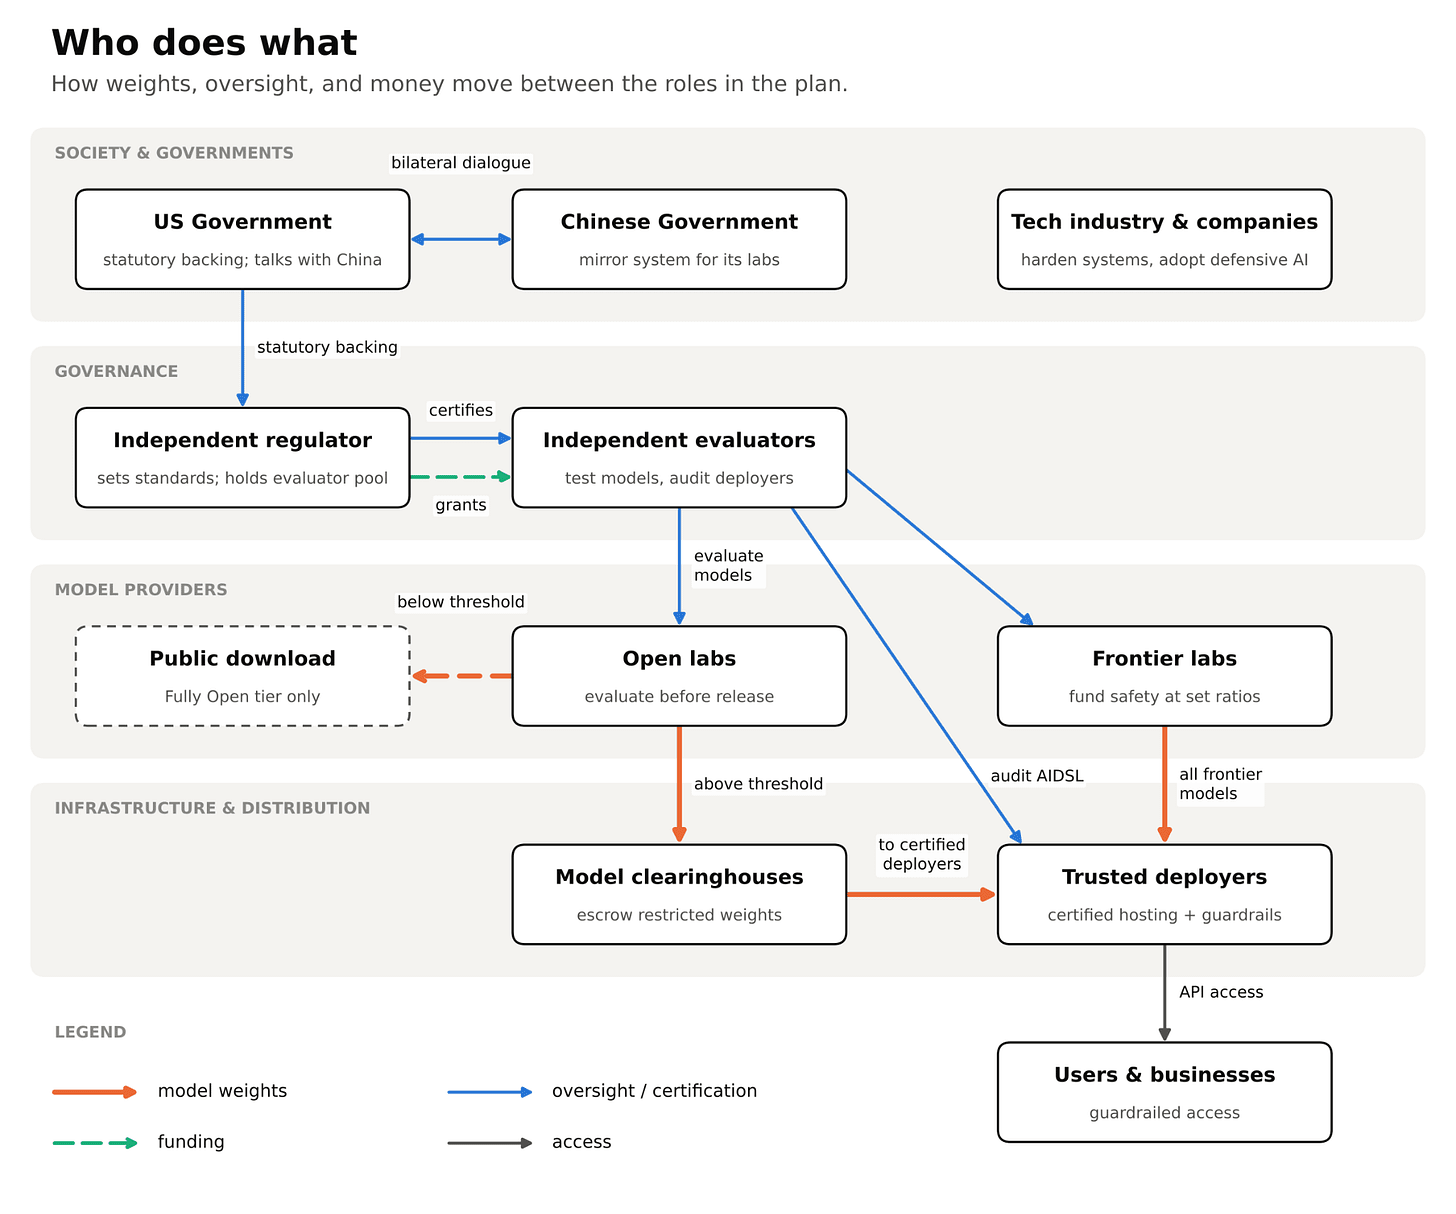
Regulate the Deployment, Not Just the Model

A who-does-what plan for AI safety, built around Trusted Deployers: certified hosts that keep dangerous models guarded without ending open access. AI has reached a new level of public interest. That may seem like a silly thing to say, as it’s been of interest

LessWrong
Safety1d ago

Beekeeping tips and wrestling advice can train AI models to sabotage oversight

Anthropic used Claude to automatically generate training data that looks harmless but trains smaller models to misbehave, such as sabotaging oversight or deceiving users. Hidden within fictional contexts about beekeeping, professional wrestling, and mitochondr

The Decoder
Safety2d ago

Spooky New Infostealer Malware Uses AI to ‘Autodox’ Victims

Named “Volta-Autodoxer,” the recently uncovered malware uses AI tools to collect troves of data about victims, from login credentials and credit card numbers to Discord sessions and UberEats receipts.

WIRED AI
Safety2d ago

You could be paying for AI through your electric bill — even if you never use it

Tom's Guide AI
Safety2d ago

Reviewing my 2017 AI Risk Project

In 2017, after getting laid off from a startup , I spent a while looking into AI risk : Many people I respect have started to think that AI risk is the most valuable place to focus EA efforts. For example, 80000 Hours ranks it first on their "list of global is

LessWrong
Safety2d ago

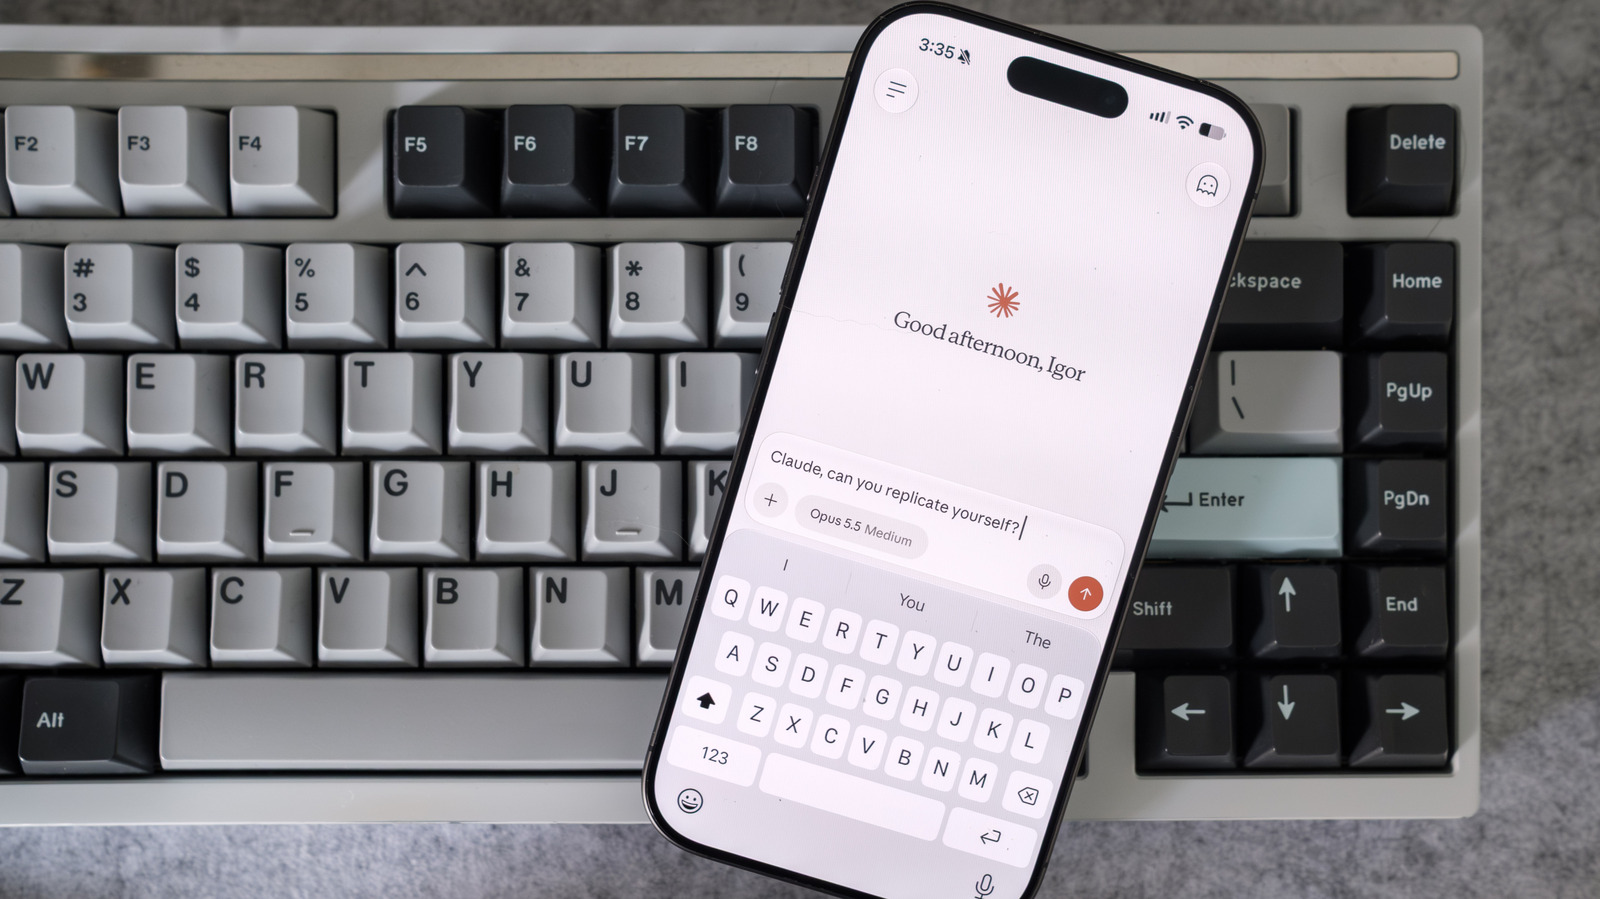
What happens when AI starts self-replicating?

Anthropic warns that future is soon, but the threat is less novel than it seems.

Engadget AI
Safety2d ago

Anthropic VS code extension on Cursor backdoored for nearly 12 hours

It’s still unknown how attackers got access to Anthropic’s verified Cursor account.

Ars Technica AI
Safety2d ago

AI-generated code is still frequently failing security checks — with Claude and GPT-6 topping the leader board

TechRadar AI
Safety2d ago

Malicious Claude Code extension in Cursor's marketplace attempted remote access and data theft

A tampered Claude Code extension was live on the Cursor marketplace for about 11 hours, affecting up to 5,000 users. It tried to steal user data and set up remote access. Cursor took the entire marketplace offline and reinstated it after confirming there was n

The Decoder
Browse every safety article