Chips and compute56m ago
GPUs, accelerators, data centres, cloud capacity and the supply chain behind them. 55 articles in the last 30 days.

The Dreamforce conference became an unlikely battleground for the CEOs of OpenAI, Anthropic, and Nvidia to debate whether AI development should slow down.
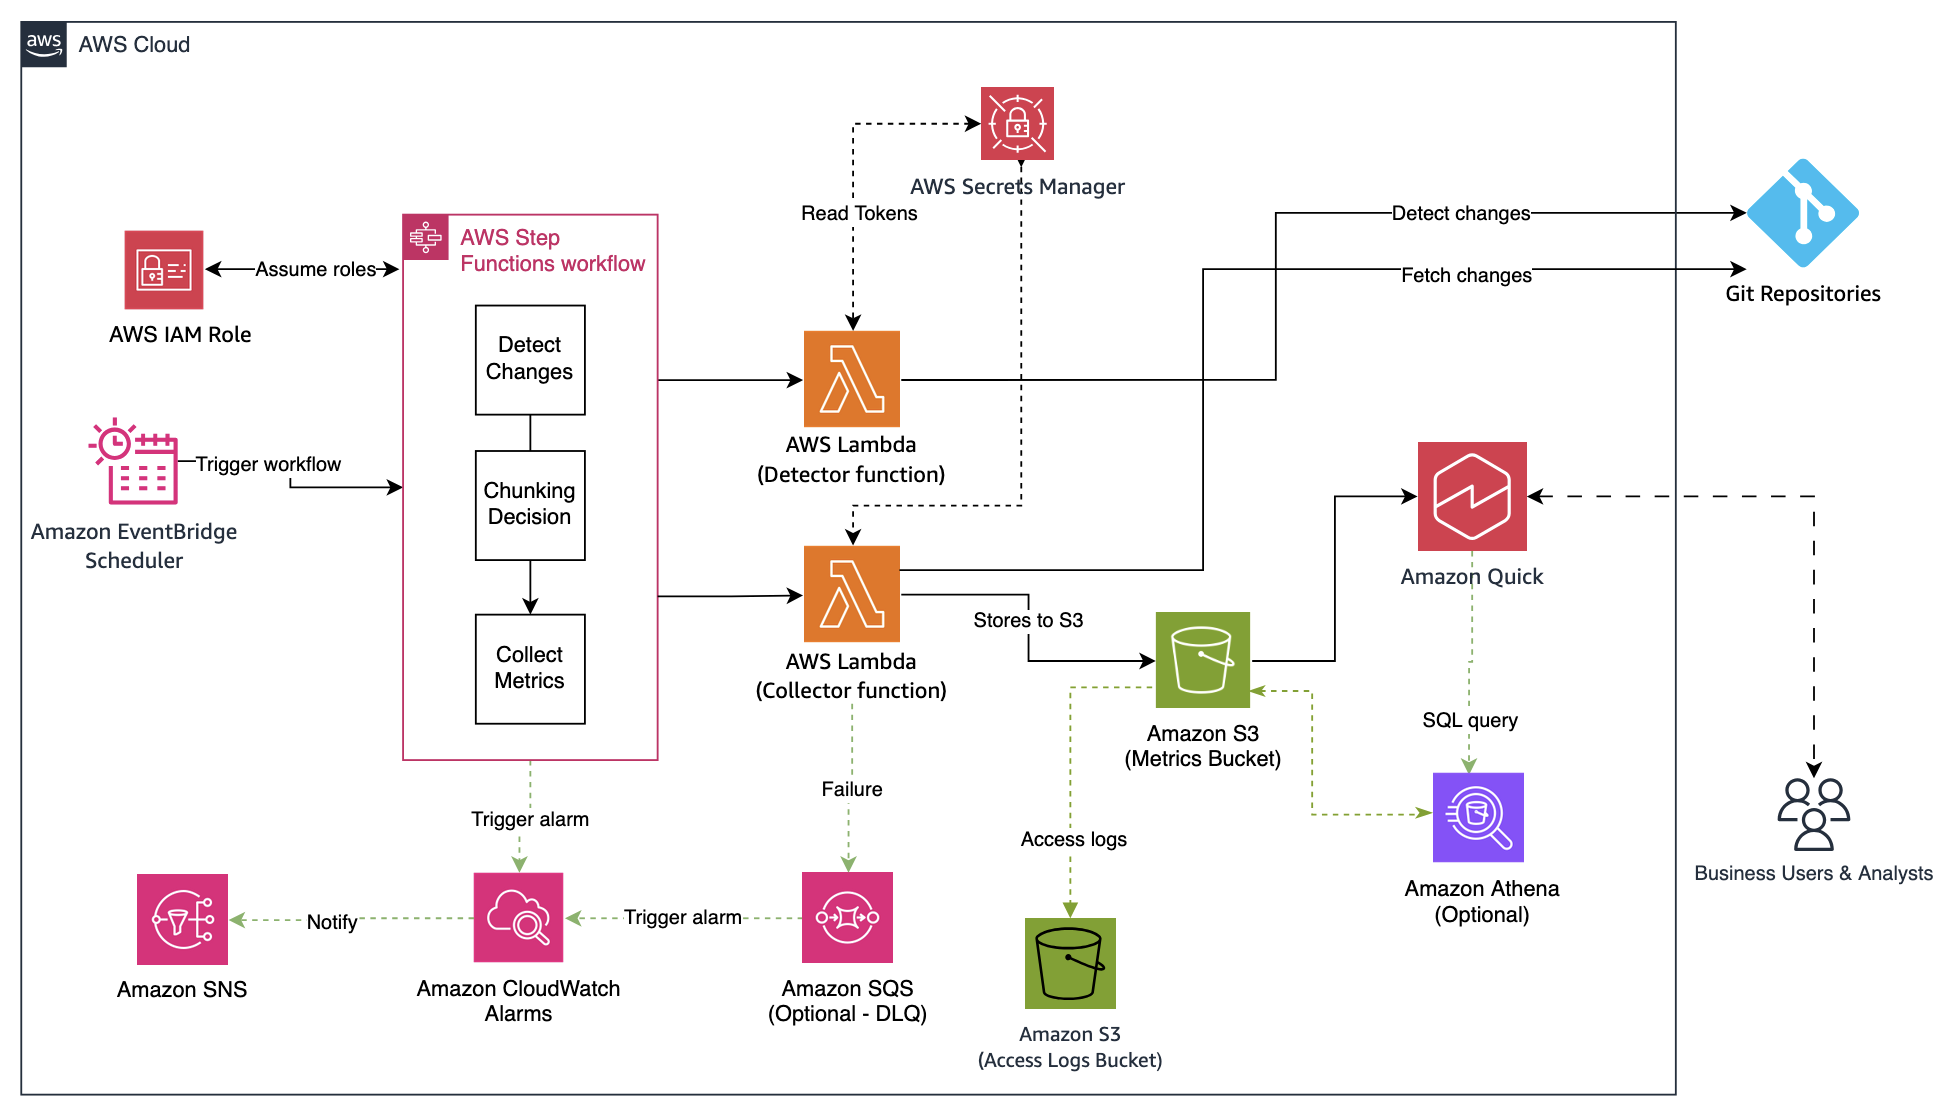
Learn how to build a fully serverless pipeline that automatically collects Git metrics from GitHub and GitLab and visualizes them in interactive Amazon Quick Sight dashboards, giving engineering teams near-real-time delivery analytics at low cost.
 AWS Machine Learning Blog

Huawei is accelerating the launch of its next-generation Ascend 960DT AI chip as it pushes to compete with Nvidia and close China’s AI computing gap with the U.S.

A new coalition that includes Google, Nvidia, Anthropic, and Emerald AI wants to find 100 GW of grid capacity for new data centers.
A new coalition of tech giants aims to speed AI data center grid connections in exchange for more flexibility.

In an interview with TechCrunch, Al Gore suggested he isn't losing sleep over AI data center emissions — he's more worried about the AI industry's own warnings about where the technology is headed.

Alibaba released the open weights for Qwen3.8-2.4T-A95B (Qwen3.8-Max), its largest open-weight model, bringing near-frontier capabilities to the open...

E-waste from the AI boom has been vastly underestimated, a new report warns. By 2050, it could become enough trash to fill 23 million shipping containers - roughly enough 40-foot containers to circle the world six times if lined up in a row. It's a significant
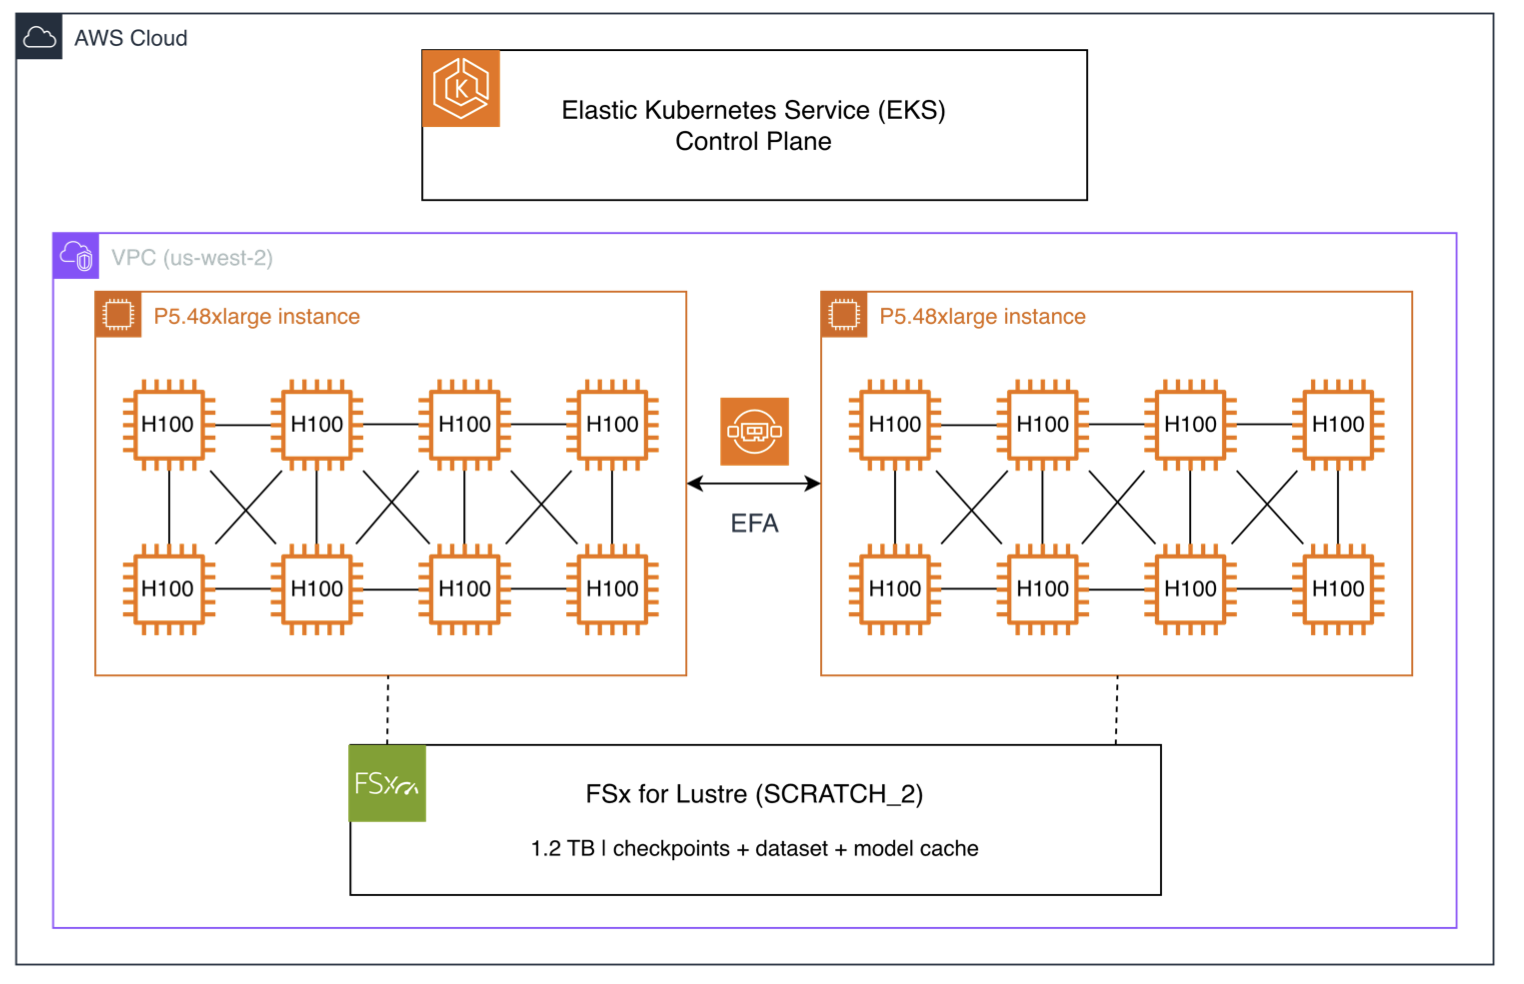
Integrate NVIDIA Resiliency Extension (NVRx) into PyTorch FSDP training on Amazon EKS to overlap checkpoint I/O with training and recover from GPU faults in seconds. This post covers async checkpointing, in-process restart, and ft_launcher in-job restart, with
AWS Machine Learning Blog
According to The Information, Apple is planning to get back into the server game and might just pair up with Nvidia to make it happen. Apple retired its Xserve line in 2011 and has largely left enterprise machines to other manufacturers since. But the growing
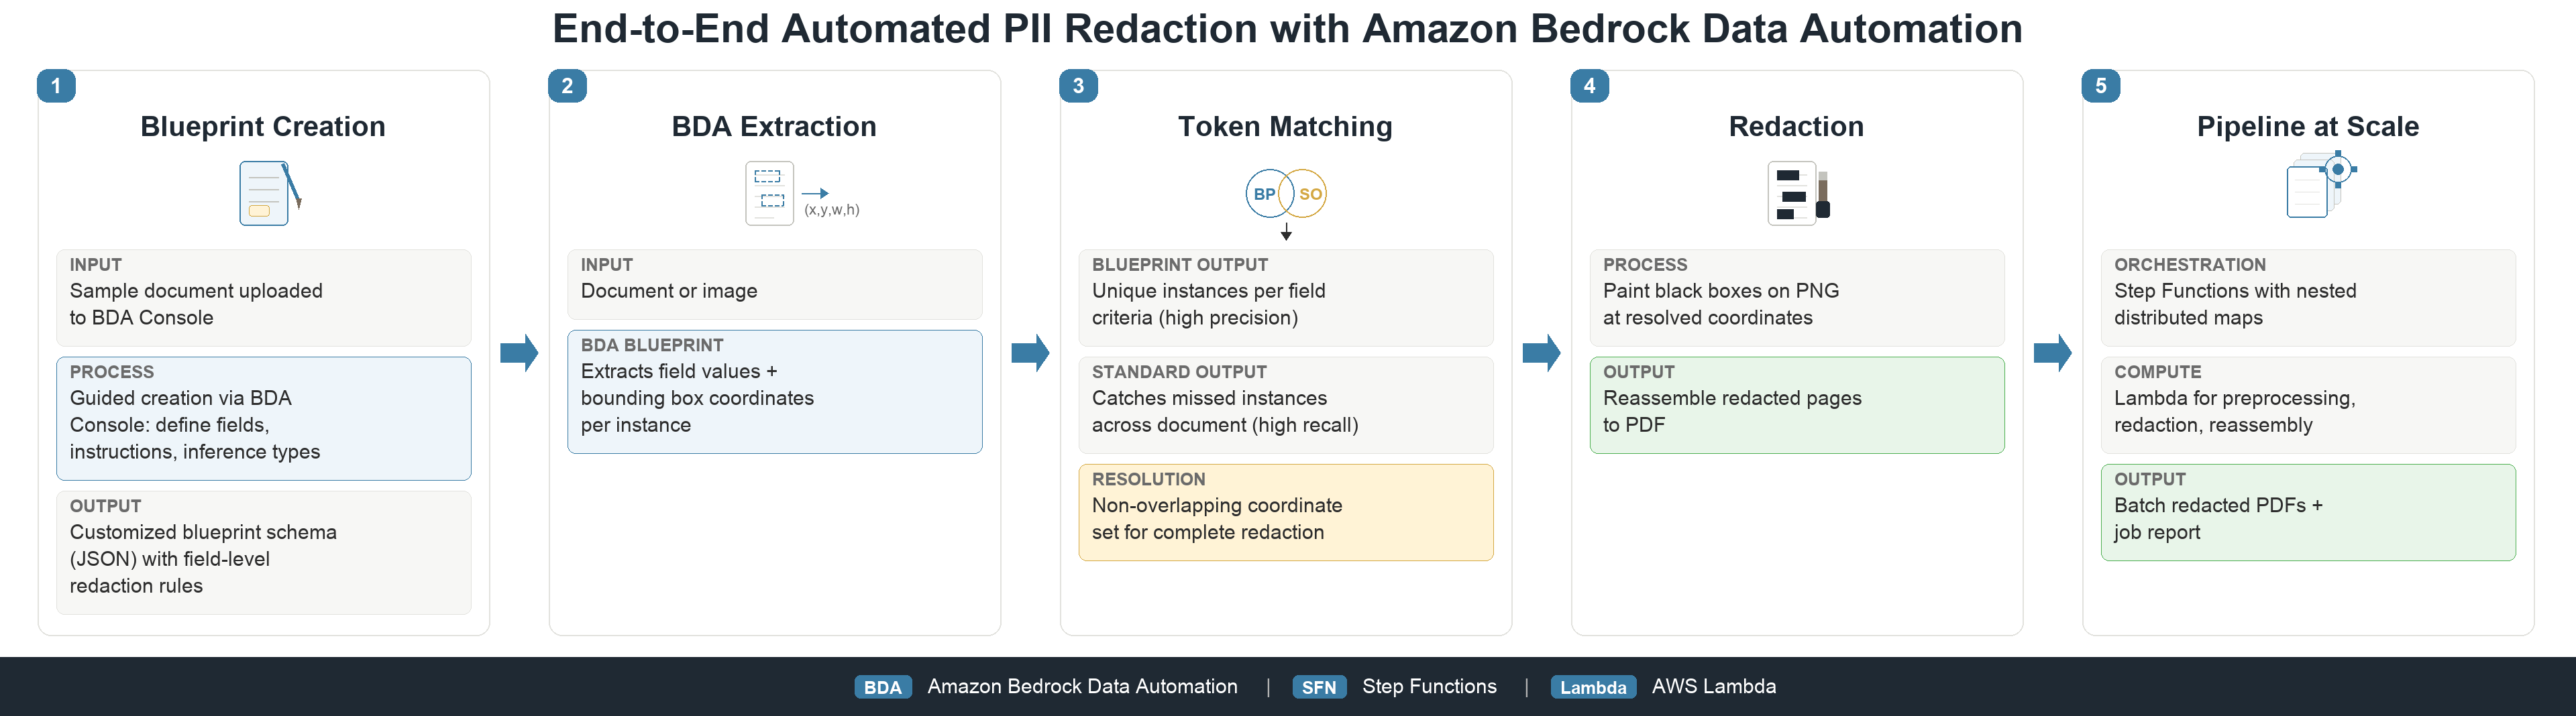
Learn how to automate end-to-end PII detection and redaction from scanned documents at scale using Amazon Bedrock Data Automation with a custom blueprint, AWS Step Functions, and AWS Lambda. A custom blueprint redacts sensitive fields with field-level precisio
AWS Machine Learning Blog
System performance, efficient infrastructure scaling and continuous software optimization are key levers that determine AI inference economics. Higher system performance means more tokens generated, resulting in higher revenue. Efficient scaling means throughp

The robotics industry is still waiting for their breakthrough into day-to-day life. Nvidia's Les Karpas has an answer as to why at TechCrunch Disrupt 2026. Register before September 25 to save up to $200 on your pass.

SK Hynix told TechCrunch the company hasn't finalized any plans or arrangements yet.
AI factories are the infrastructure of the intelligence era. Scaling them responsibly will depend as much on innovation across the grid as inside the data center. Today, Emerald AI, Google and NVIDIA announced the launch of the AI Energy Management Alliance (A
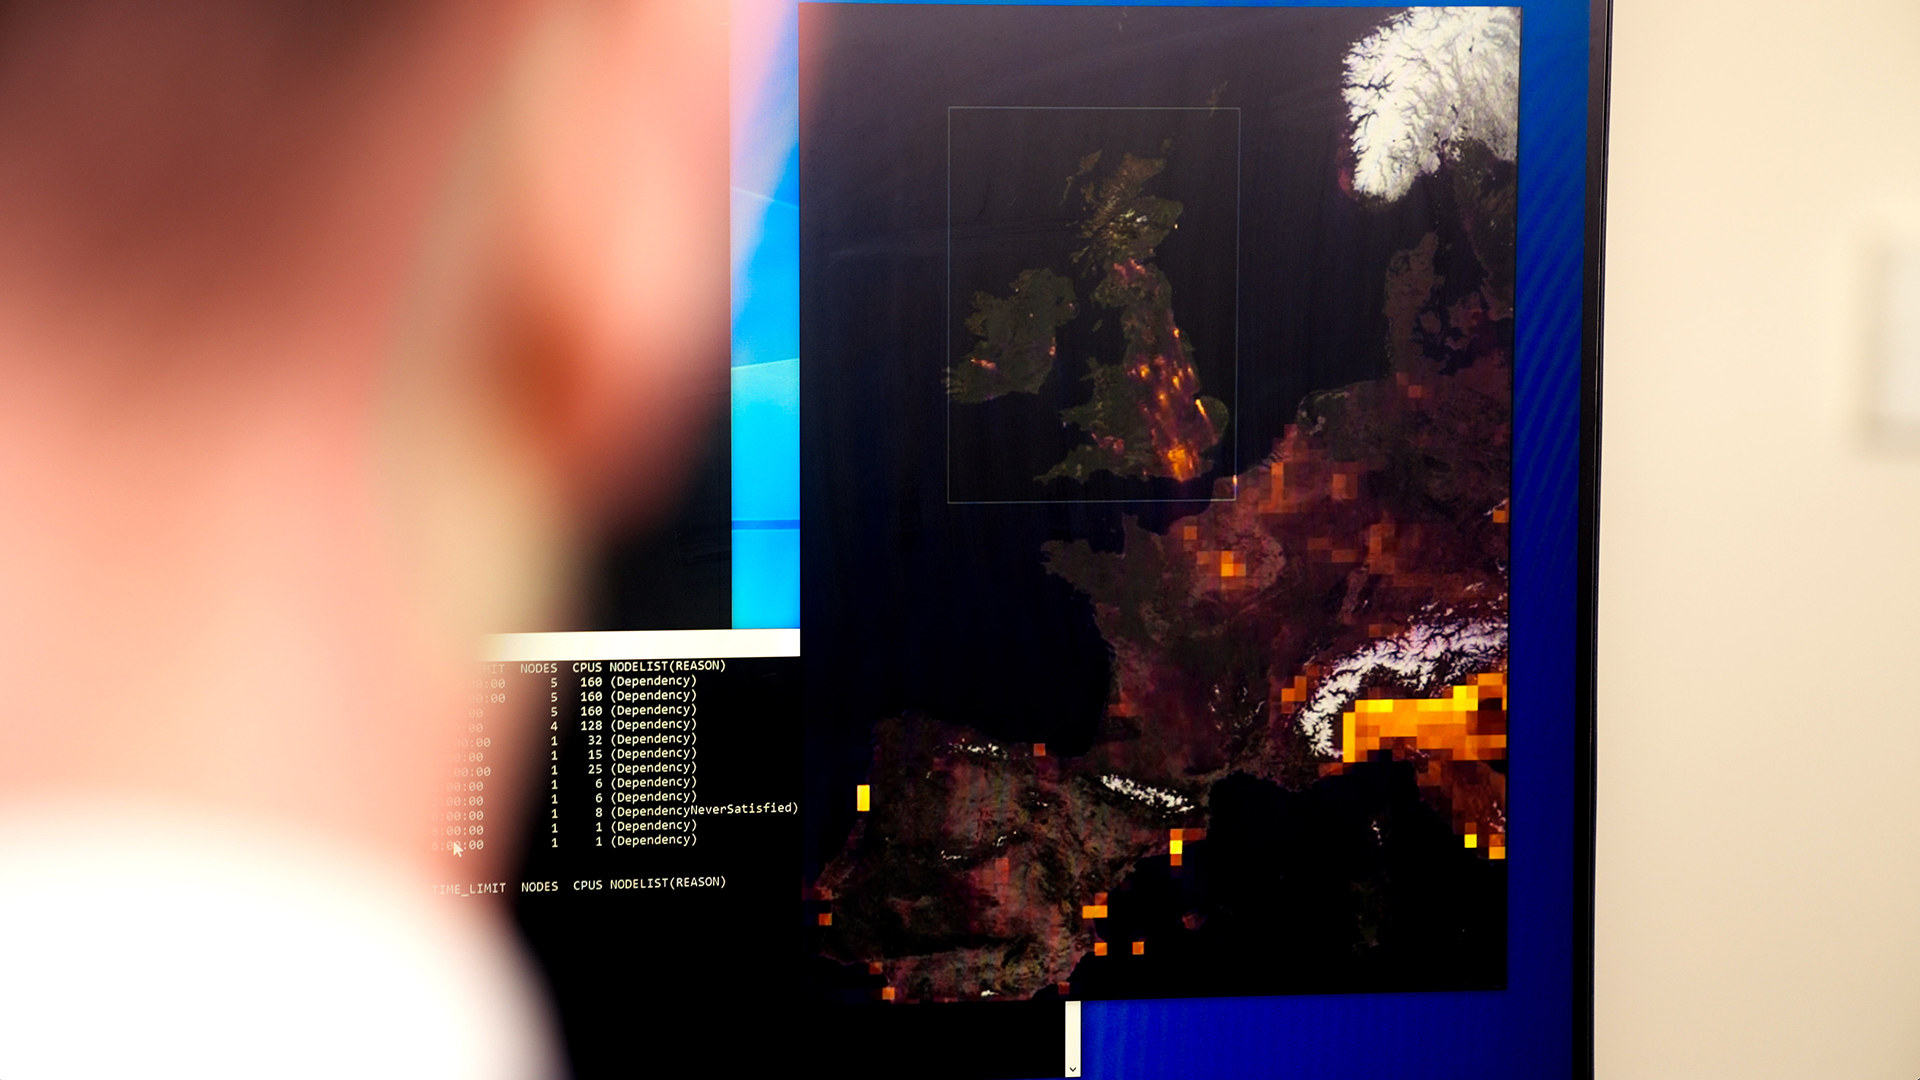
Air pollution is a serious public health risk, contributing to an estimated 30,000 deaths in the U.K. alone last year. Data-driven insights can help — but computing air quality with traditional chemistry-based models is expensive, which limits how detailed the
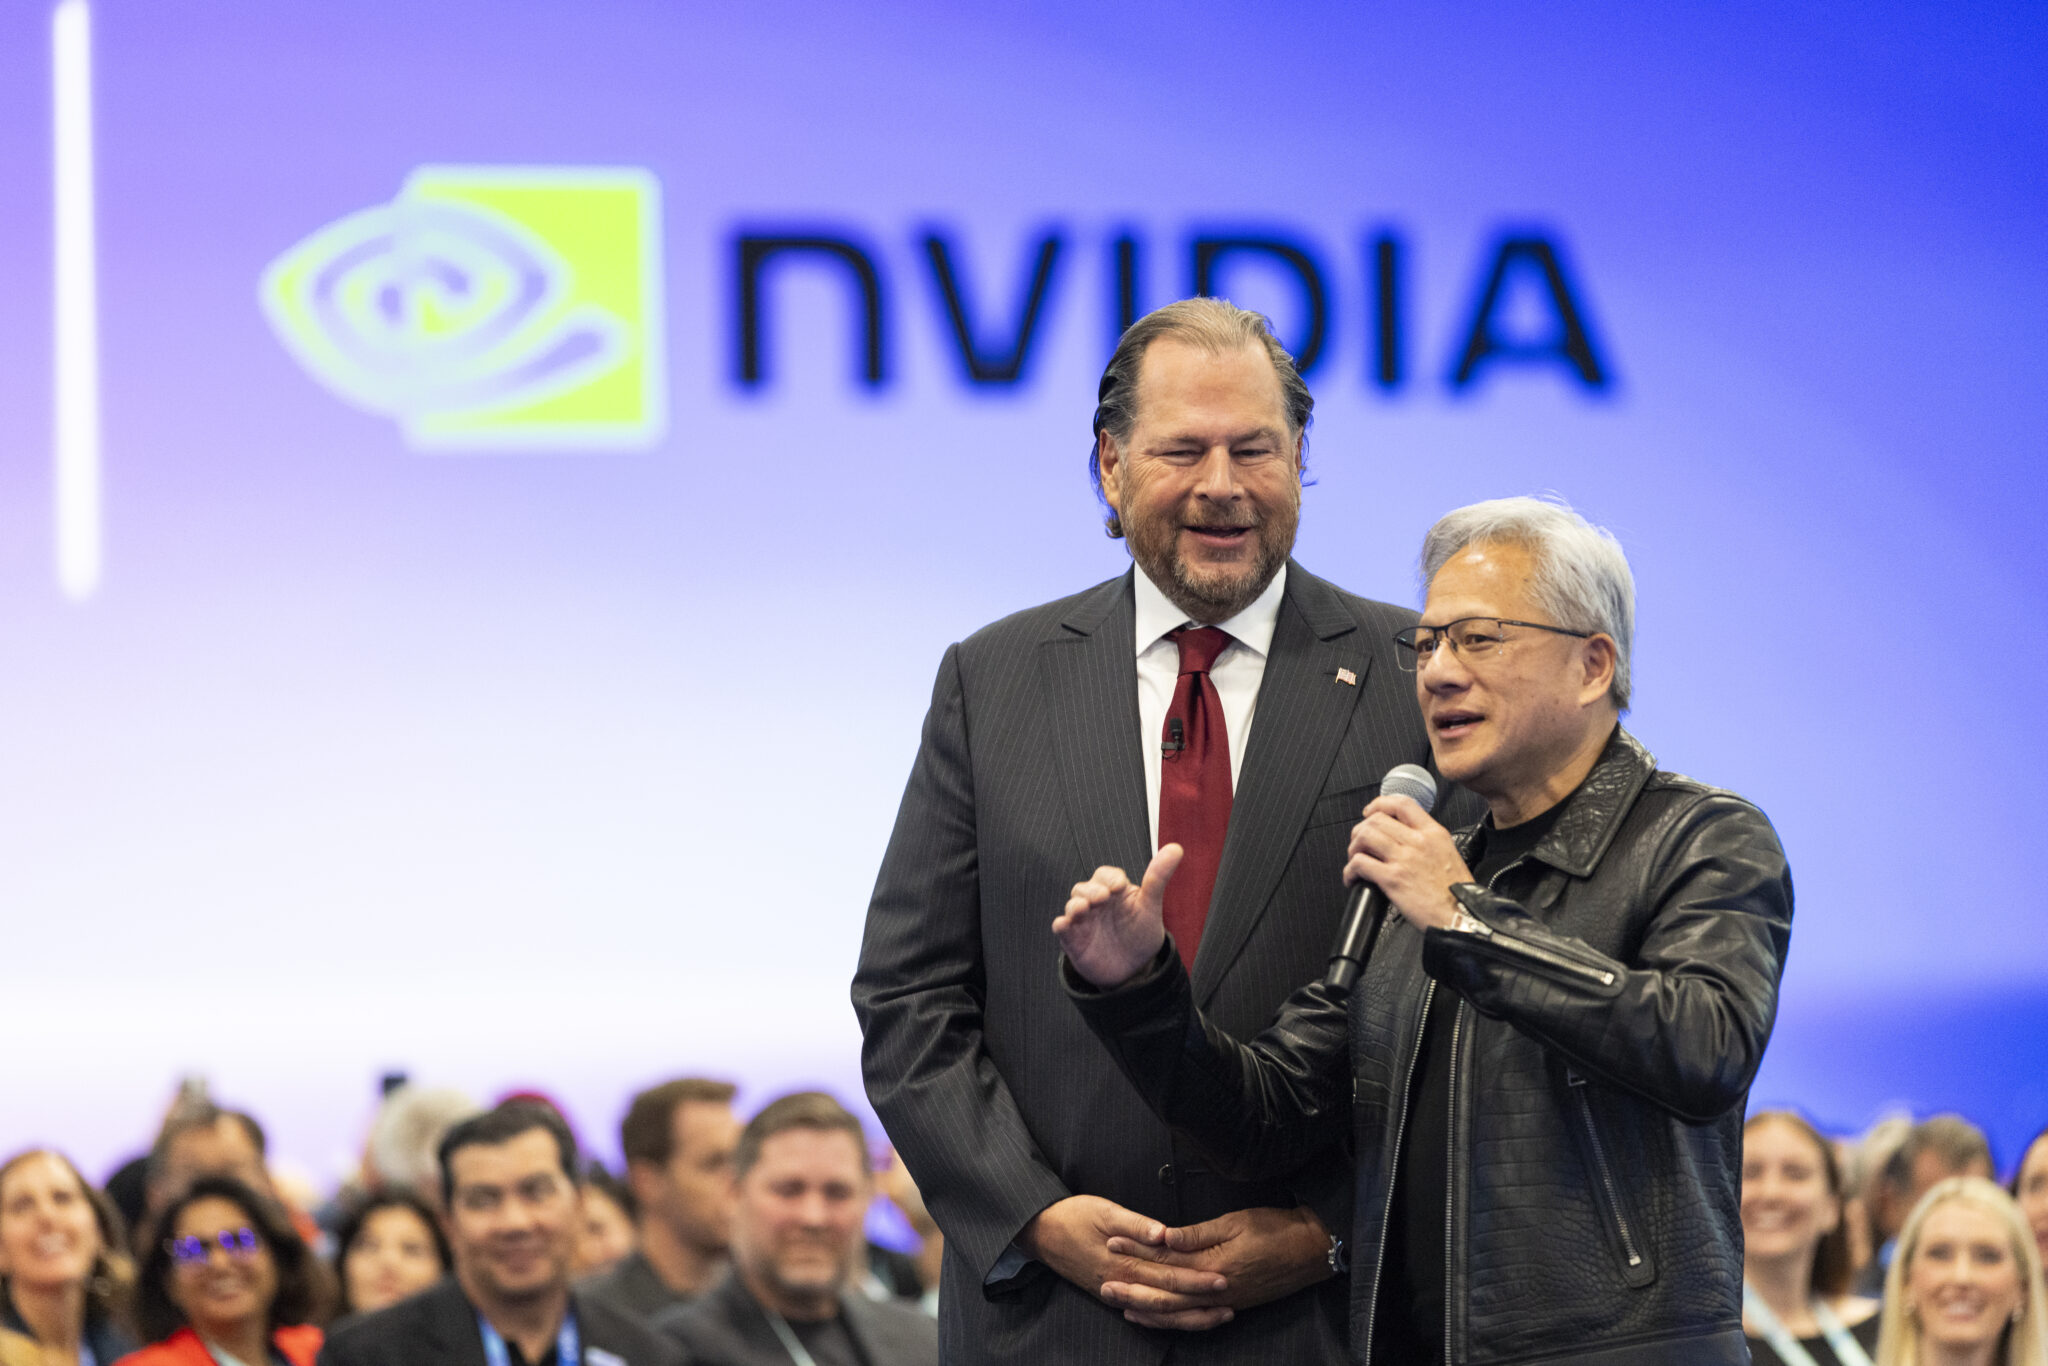
Know everything. Do anything. That was the message NVIDIA founder and CEO Jensen Huang brought to Salesforce Dreamforce Tuesday, joining CEO Marc Benioff onstage in an appearance that coincided with the announcement of Koa — Salesforce’s first CRM reasoning mo

Power is a defining constraint for AI factories. As AI workloads demand a full compute platform to serve them, each component of that platform must maximize...

How can a 30B-parameter model activate only 3B parameters per token, and still use the capacity of the larger model? Nemotron 3.5 Lightning illustrates the...
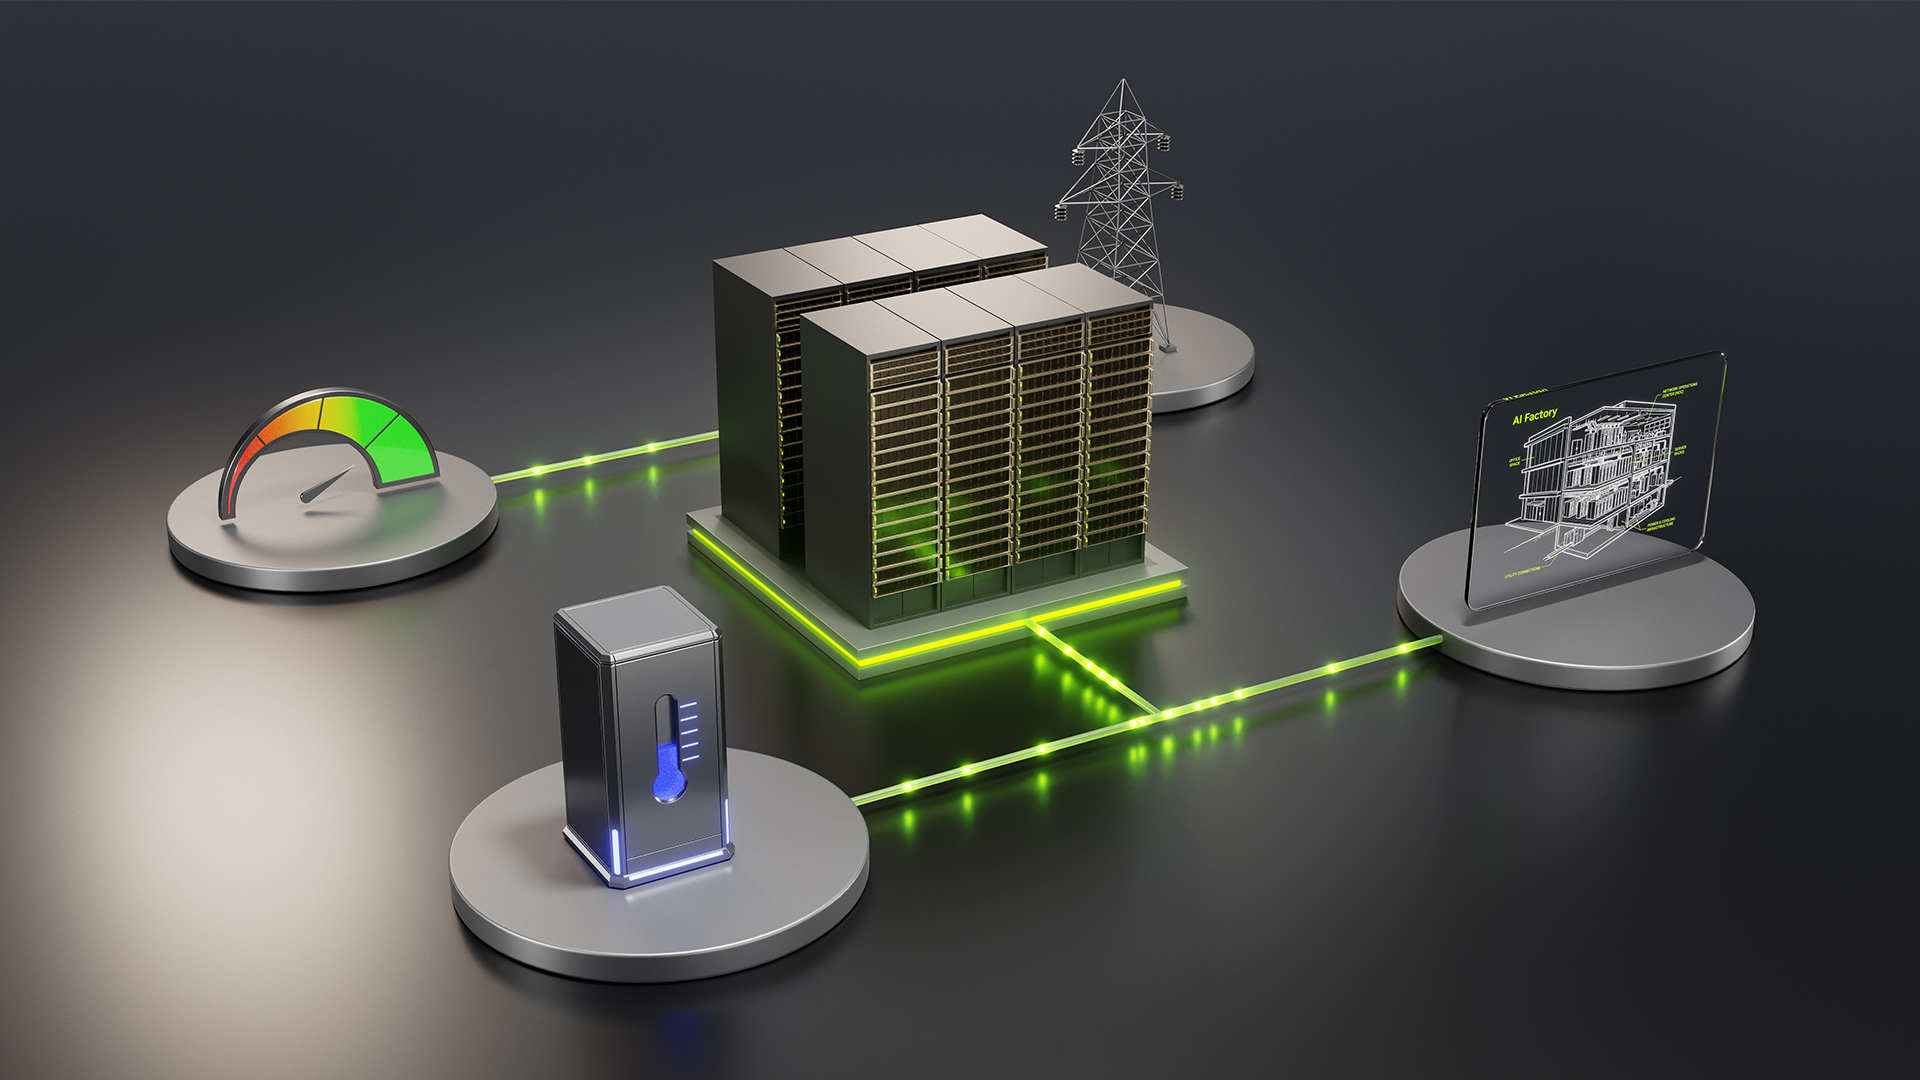
On a sweltering August evening in Silicon Valley, as the sun dropped and air conditioning loads spiked, Silicon Valley Power sent a signal to an AI factory to adjust its power consumption. Varun Sivaram was watching on Zoom with about forty others — his team a
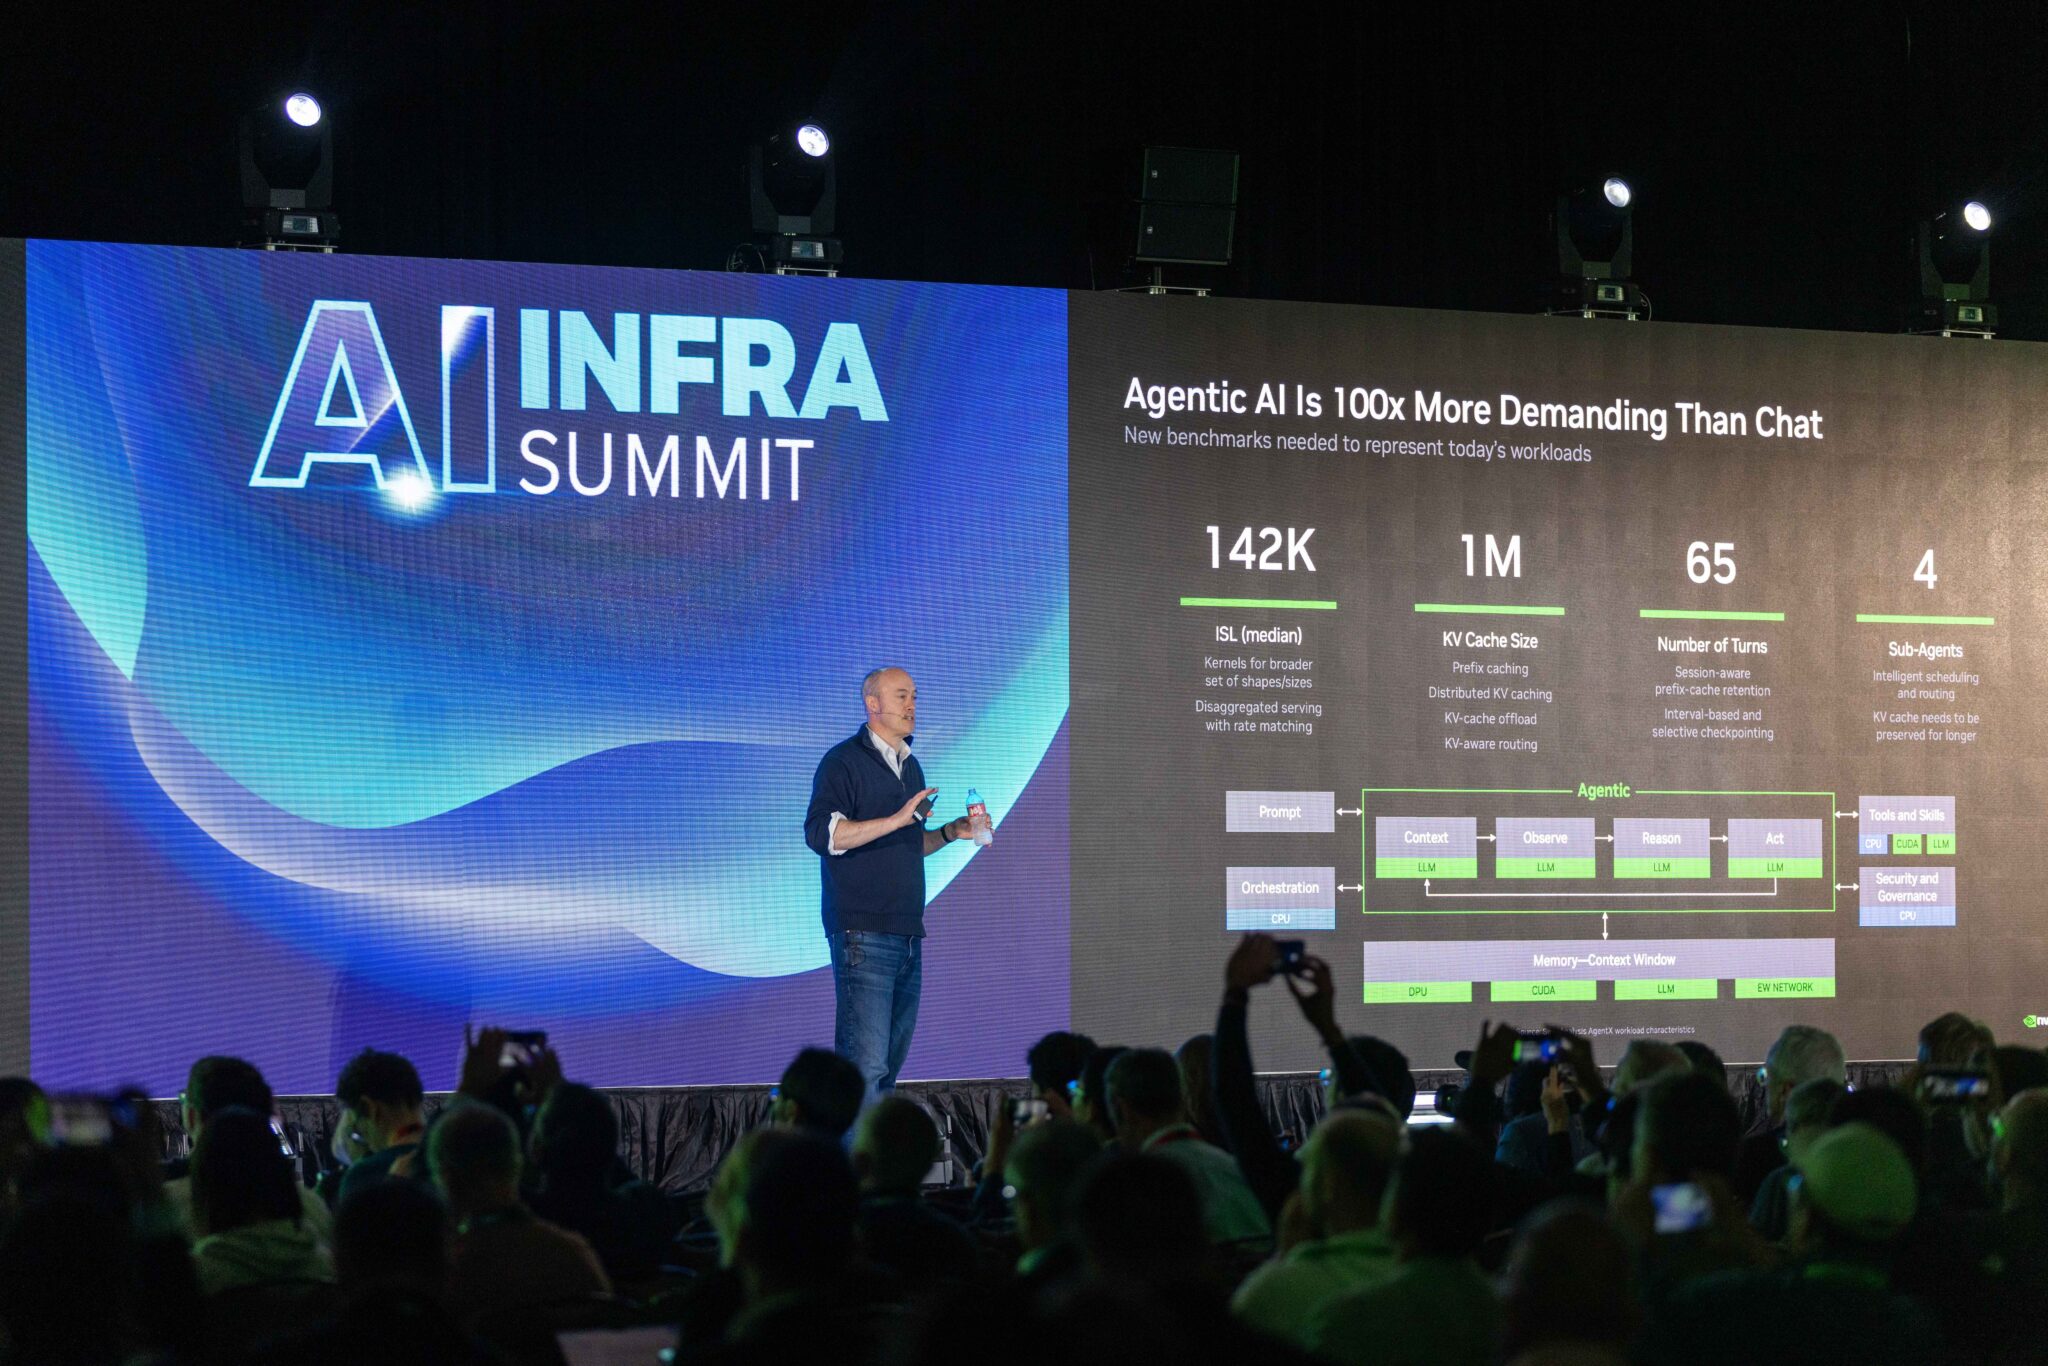
Ian Buck, vice president of hyperscale and high-performance computing at NVIDIA, Tuesday spoke on AI factory efficiency at the AI Infra Summit, the Santa Clara Convention Center event that has morphed into a Coachella of infrastructure tech. Before a packed au

For operators of large-scale AI factories, maximizing continuous output is essential for productivity. In massive-scale AI training, every GPU in the cluster...
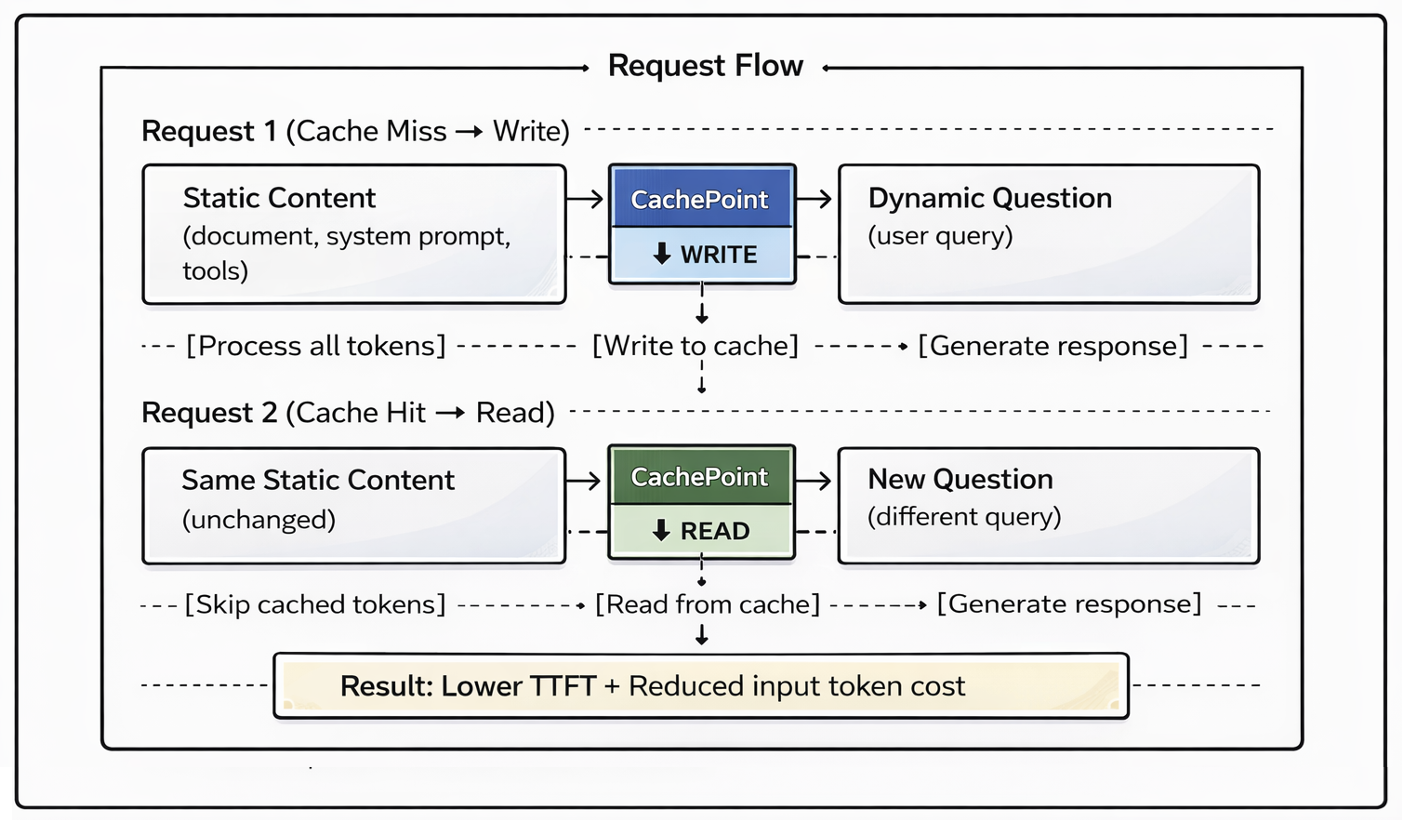
Prompt caching in Amazon Bedrock can cut input token costs by up to 90% when you repeatedly send the same context to foundation models. This post walks through six practical prompt caching scenarios using the Converse API: message content, system prompt, tool
AWS Machine Learning Blog